Model the service before operating it
The official Minecraft server page is enough to get through one launch: obtain the JAR, confirm that Java works, read and accept the EULA, and run the server. A successful launch proves only that the files could be combined at that moment. Long-term operation also has to absorb dependency drift, continuous world writes, extension code, network exposure, host failures, and irreversible data migrations.
This essay covers a single Minecraft Java Edition instance on Linux, managed by systemd and shared among friends. Paper provides concrete examples for observability and updates; Vanilla, Fabric, Forge, and NeoForge require their own launch scripts and compatibility sources. A large public network also needs proxy architecture, DDoS protection, multi-tenancy, moderation, and commercial compliance, all beyond this scope.
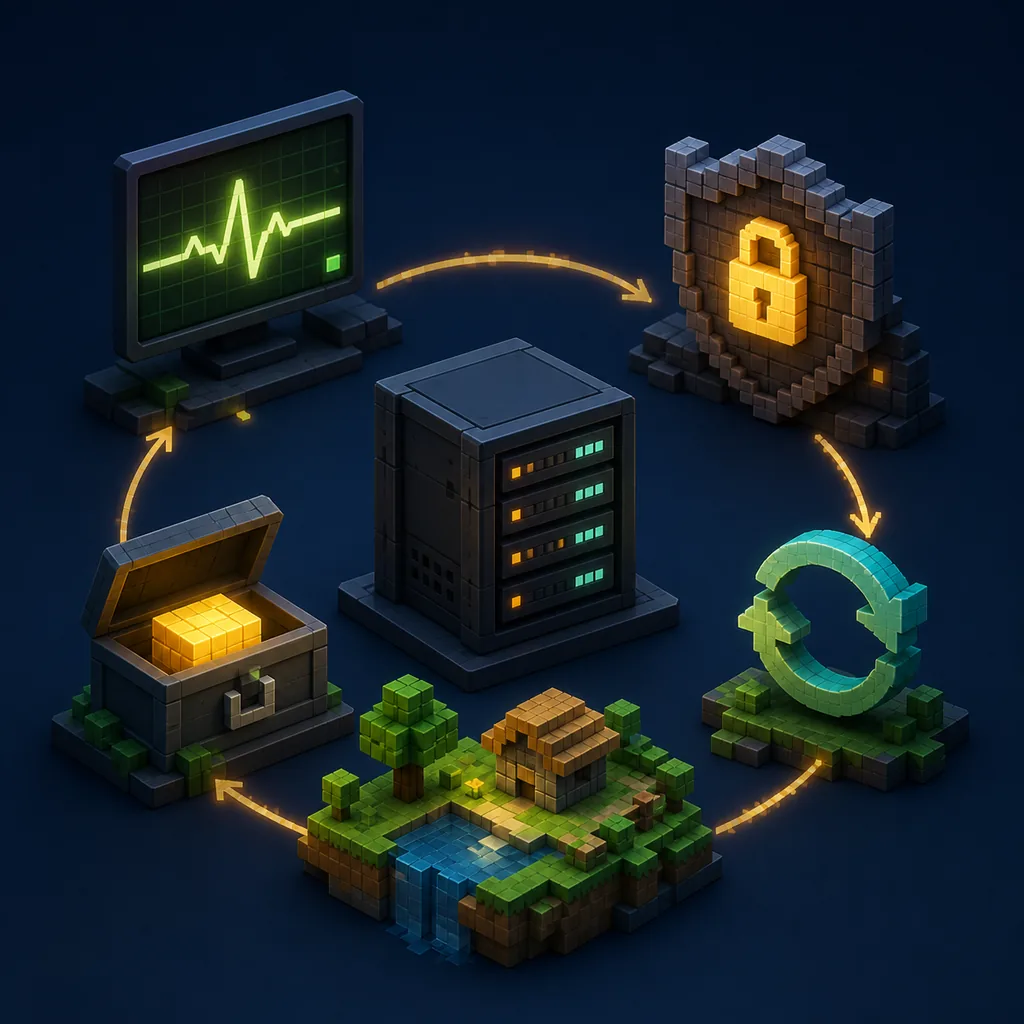
Splitting the server into four classes of objects gives every later operation a defined target:
| Object | Typical contents | Consequence when uncontrolled |
|---|---|---|
| Executable dependencies | Java, server build, loader, mods, plugins, data packs | Startup failure, behavior drift, supply-chain exposure |
| Configuration and identity | Launch arguments, server.properties, allowlist, operator privileges, credentials | Default drift, excess privilege, private-data disclosure |
| Mutable state | Worlds, player data, advancements, statistics, mod or plugin data | Lost progress, format migration, concurrent-write damage |
| Operational evidence | Logs, version manifests, backup records, restore reports, profiles | An unexplained failure and no proof that recovery works |
Mutable state supplies the decisive constraint: at any instant, exactly one authorized server process may write a production world. Test servers, restore drills, and upgrade copies need separate directories and separate network entry points. Containers, panels, filesystem snapshots, and automatic restarts do not change this single-writer constraint.
Constrain every decision with four invariants
I now use four invariants to decide whether a server is maintainable:
| Invariant | Acceptable evidence | Common illusion of success |
|---|---|---|
| Single writer | One process writes the production world; test copies use isolated paths and ports | Two instances target one world because “one is only for looking” |
| Reproducible | Exact versions, origins, hashes, Java, arguments, and configuration rebuild the same instance | Remembering “use latest,” “about 4 GB,” or retaining one JAR |
| Recoverable | A backup boots in an empty location, and an ordinary player writes, restarts, and reads state back | A zero exit code from an archive job or a snapshot on the same disk |
| Observable | Signals cover process, game loop, player path, capacity, and recovery, each tied to a decision | A live process, a displayed 20 TPS, or a nonempty backup file |
An operation should create a reviewable artifact. An upgrade creates a new manifest and acceptance record. A backup creates a copy in another failure domain and a restore report. An alert opens an executable diagnostic branch. Without those artifacts, the next operator still depends on memory and guesswork.
Build a reproducible compatibility manifest
Compatibility belongs to an exact combination. Paper’s version and Java requirements, the NeoForge user guide, and Fabric’s server installation guide all distinguish Java requirements by game release. Those tables change as new game lines arrive. Record the combination actually in use, then reopen the documentation for that exact line before every upgrade.
A minimum manifest contains:
- the exact game version, server implementation, and build;
- loader or installer version, plus every generated launch script, argument file, and dependency directory;
- the absolute Java executable path, distribution, major release, and complete
java -versionoutput; - every mod, plugin, data pack, and dependency, with exact version and official project page;
- SHA-256 values for the server and extension JARs;
- the complete launch command, JVM arguments, operating system, and architecture;
- world roots, extension-data roots, and a sanitized configuration diff;
- creation time, the previous recoverable release, and the last restore drill.
The YAML below shows structure only. Replace every angle-bracket field with a real value. Credentials, player UUIDs, IP addresses, and private paths do not belong in a public repository.
schema: 1
created_at: 2026-08-11T09:30:00+08:00
minecraft: "<exact-game-version>"
server:
  implementation: "<vanilla-paper-fabric-forge-neoforge>"
  build: "<exact-build-or-loader-version>"
java:
  executable: "/absolute/path/to/java"
  version: "<full-java-version>"
launch:
  command: "<exact-command-or-generated-script>"
  jvm_args: ["-Xms2G", "-Xmx4G"]
content:
  - name: "<mod-or-plugin>"
    version: "<exact-version>"
    source: "<official-project-url>"
    sha256: "<sha256>"
state_roots: ["<world>", "<plugin-data>"]
A hash answers “did this file change after it was recorded?” It cannot answer “was the download source trustworthy?” Obtain the file from Mojang or the project’s official distribution point first, then record both origin and hash. Verify an upstream signature or published digest separately when one exists. JARs in the manifest are private runtime assets; do not republish Mojang software with a public repository.
The operator still reads and accepts the license personally on first launch. A public or paid server also needs periodic review of the changeable Minecraft Usage Guidelines. A private recovery bundle may retain the acceptance state, but a script should not make that decision for its operator.
Draw trust boundaries before choosing reachability
Minecraft has more than one privilege layer. Ordinary players are bounded by the game protocol and command permissions. Operators can change worlds and players. Mods and plugins execute inside the server process. Paper’s plugin installation guide explicitly warns that plugins receive unrestricted access to both the server and its host. The operating system sees one Java process, so extension code inherits everything the service account can reach.
| Principal | What it can affect | Primary controls |
|---|---|---|
| Untrusted player | Game protocol, chat, available commands, gameplay mechanics | Online account verification, player allowlist, command permissions, server updates |
| Operator or panel account | Console, worlds, players, and configuration | Separate identities, least privilege, strong authentication, audit, prompt removal |
| Mod or plugin | Java process, service directory, network, and every file readable by the service account | Trusted origin, version review, dedicated OS account, filesystem sandbox |
| Host administrator or provider | Entire process, memory, disk, and backups | Host trust, OS maintenance, disk encryption, provider boundary |
| Backup operator | Historical worlds, player identity, configuration, and secrets | Encryption, access control, offline or immutable copies, retention limits |
A server among friends usually has one of three reachability designs:
| Design | Game entry point | Management entry point | Applicability |
|---|---|---|---|
| LAN or private VPN | Reachable only by invited network members | SSH or the panel remains private too | The smallest exposed surface for a fixed group |
| Direct Internet | Only the game port is open to expected sources or all players | SSH, panel, RCON, and similar services remain source-restricted or inside a VPN | Must cover host firewall, cloud rules, IPv4 and IPv6, and Internet attacks |
| Proxy network | Players reach only the proxy; backends accept only proxy traffic | Backend management remains private | Requires implementation-specific secure forwarding, secrets, and firewalls; a separate architecture |
A small invite-only server with direct connections should retain account verification and use a player allowlist. Paper’s server.properties reference documents online-mode, white-list, the game port, RCON, and status endpoints separately. online-mode=false belongs only to a backend already isolated and configured for secure forwarding under its proxy documentation. Paper’s Velocity security guide likewise states that a forwarding secret does not replace a firewall.
Converge the network in this order:
- Decide who needs to reach the game port and who needs to reach the management plane.
- Deny unsolicited inbound traffic, then allow only necessary protocols, ports, and sources.
- Check the cloud security group, router, host firewall, IPv4, and IPv6 together.
- Test once from an allowed network and once from a disallowed network, then retain a rules snapshot.
- Keep management credentials and player-permission data in the private runtime environment.
Ubuntu’s firewall documentation describes ufw as an IPv4 and IPv6 host firewall. Port forwarding creates reachability, DNS supplies a name, and the player allowlist filters game logins. None of the three alone provides host access control.
Let systemd manage the process and the service account bound the damage
Run the server under a dedicated system account with no interactive login and no sudo rights. The simplest path boundary lets that account write only the instance directory. A tighter deployment also gives the maintenance identity ownership of Java, the server JAR, and mod or plugin JARs, leaving only worlds, logs, and extension data writable. Test the exact split against the real loader and extension set.
The unit below is a skeleton for a Vanilla or Paper-style direct JAR launch. Its Java path, heap sizes, directories, filename, and stop timeout are examples. Loader-generated scripts and argument files for Forge, NeoForge, and similar stacks must enter the manifest as the complete ExecStart chain.
[Unit]
Description=Minecraft Java server
After=network.target
StartLimitIntervalSec=5min
StartLimitBurst=3

[Service]
Type=simple
User=minecraft
Group=minecraft
WorkingDirectory=/srv/minecraft/instance
ExecStart=/usr/bin/java -Xms2G -Xmx4G -jar server.jar nogui
Restart=on-failure
RestartSec=10s
TimeoutStopSec=5min
UMask=0027

NoNewPrivileges=true
PrivateTmp=true
PrivateDevices=true
ProtectSystem=strict
ProtectHome=true
ReadWritePaths=/srv/minecraft/instance
ProtectKernelTunables=true
ProtectKernelModules=true
ProtectControlGroups=true
ProtectClock=true
ProtectHostname=true
RestrictSUIDSGID=true
LockPersonality=true
CapabilityBoundingSet=
AmbientCapabilities=
RestrictAddressFamilies=AF_UNIX AF_INET AF_INET6
SystemCallArchitectures=native

[Install]
WantedBy=multi-user.target
Four boundaries in this skeleton require real tests:
-
Restart=on-failureattempts recovery after abnormal termination, while an explicitsystemctl stopdoes not immediately bring the service back. Start-rate limits cap a crash loop.systemd.service(5)defines exit codes, signals, and restart conditions precisely. -
TimeoutStopSecmust exceed the slowest normal save. The logs should show a completed world save and shutdown; systemd may force termination after the timeout. - Do not copy
SuccessExitStatus=143mechanically. A direct Java process receivingSIGTERMand a shell wrapper returning 143 are distinct states. The actual launch chain determines the correct interpretation. - The example deliberately omits
MemoryDenyWriteExecute.systemd.exec(5)says it is incompatible with programs such as JIT engines that generate code at runtime; the JVM needs a JIT.
For each added sandbox directive, launch an isolated instance, join the world, exercise critical extensions, save, and stop normally. At minimum, run after deployment:
sudo systemd-analyze verify /etc/systemd/system/minecraft.service
sudo systemd-analyze security minecraft.service
systemd-analyze security evaluates only the sandboxing features implemented by systemd. A lower exposure score does not prove that plugins are trustworthy, game permissions are correct, or the network is isolated.
Capacity planning starts with a real workload and a 50 ms budget
“How much RAM supports how many players?” omits the variables that decide the result: game and server release, mods or plugins, view and simulation distance, generated terrain, entities, redstone, storage latency, and player behavior. A capacity test fixes a set of representative scenarios, then compares matching time windows.
| Scenario | Evidence to observe | Main failure exposed |
|---|---|---|
| Cold start into an existing world | Startup duration, logs, peak memory, disk reads | Dependency errors, migration, cache and storage bottlenecks |
| Peak players in explored terrain | MSPT distribution, per-thread CPU, network latency | Steady-state game loop and extension load |
| Several players generating new terrain | MSPT spikes, generation hotspots, disk writes | World generation and main or worker-thread pressure |
| Representative farms, redstone, entities, and critical extensions together | Profile hotspots, entity or chunk counts, gameplay outcome | Real gameplay cost and semantic changes |
| Save or backup overlapping online load | I/O latency, save duration, free space, player path | Background contention and disk-capacity boundary |
Minecraft targets 20 ticks per second (TPS), giving each tick a 50 ms time budget. Paper’s command reference explains the same relationship through MSPT, or milliseconds per tick. TPS is capped at 20 while healthy, and average MSPT hides spikes. Track the distribution, the share of ticks over 50 ms, and the player-visible result together.
Paper bundles spark from 1.21 and says in its profiling guide to sample while the issue is occurring. A useful profile covers the window that reproduces the lag, then explains it through main-thread work, terrain generation, entities, plugins, garbage collection, or I/O. A profile started after the server recovers describes only the healthy state.
Memory also needs layered evidence:
-
-Xmxcaps the Java heap, not process resident set size (RSS) or total container use; - the JVM also needs class metadata, JIT code cache, thread stacks, garbage-collector structures, and native memory;
- the operating system needs page cache, while backup, compression, and diagnostic tools need their own memory;
- Oracle’s Java diagnostic documentation provides Native Memory Tracking (NMT), but it has overhead and belongs to a defined native-memory investigation.
Total CPU use can likewise hide a saturated main thread. Inspect per-thread evidence and a profiler before choosing a faster CPU, a configuration change, or an extension fix. Blindly adding heap, scheduling restarts, or copying an entire JVM flag set merely changes symptoms.
View distance and simulation distance directly change the regions sent and ticked. The server.properties documentation gives them different meanings. Reducing either also changes gameplay, so retest performance, farms, spawning, visibility, and critical plugins after a change.
A comparable capacity experiment follows one sequence:
- Save the manifest, default configuration, and baseline.
- Reproduce the issue against the same world copy, player script, and time window.
- While it occurs, collect MSPT, a profile, per-thread CPU, RSS, heap, GC, I/O, and network evidence.
- Change one explainable factor at a time.
- Repeat the same scenario and compare both performance and gameplay semantics.
- Reserve disk space for world growth, one backup staging operation, logs, and any required diagnostic artifact.
Calculate the last item in absolute space and growth rate. “Ten percent free” alone cannot say whether a large world, temporary compressed archive, or diagnostic dump near the current heap size will fit.
Derive backup design from RPO, RTO, and a consistent restore
NIST SP 800-34 Rev. 1 supplies two concepts that translate cleanly into game terms. The recovery point objective (RPO) asks “how much progress may a failure lose?” The recovery time objective (RTO) asks “how soon must the server be playable again?”
| Decision question | Example answer | Requirement derived |
|---|---|---|
| How much progress may be lost? | Two hours | The newest completed, retrievable off-host backup must be younger than two hours, leaving time to alert and retry after a failed job |
| How soon must play resume? | One hour | Measured empty-directory restore, dependency preparation, world checks, player acceptance, and cutover together must stay below one hour |
| How late might corruption be discovered? | One week | Retention must cross that discovery window instead of allowing short rolling backups to erase every healthy generation |
Backup frequency alone cannot prove an RPO. A failed job, unreachable target, or archive that remains on the source disk defeats the phrase “backed up every two hours.” Monitoring must read the age of the latest completed backup that reached its intended failure domain and passed integrity checks.
For a small server, a planned shutdown gives the clearest consistency boundary:
- Prevent new joins and stop the service normally.
- Confirm completed world saves and process exit in the log.
- Back up every world, player and extension data, configuration, permission file, manifest, launch file, and required dependency.
- Produce an archive inventory, size, and integrity data.
- Place at least one copy outside the source host, source disk, and continuously online credential boundary.
- Start the service and verify the player path.
An online backup is valid only when the server implementation, snapshot layer, and backup tool document a save or quiesce procedure. Compressing or copying a directory while the server writes may combine region, player, and extension data from different save points. A filesystem snapshot freezes an instant; the application must still bring the world to a consistent state first.
The CISA recovery guide recommends offline or immutable copies of critical data and regular validation of backup availability and integrity. A friends-only server can implement that principle lightly, but one host loss, mistaken deletion, or compromised service account must not be able to destroy every copy. Backups may contain player identity, IP logs, permissions, and credentials, so protect and encrypt them like production data.
Begin a restore drill with the assumption that the original host is gone:
- Select a historical generation and prepare the exact Java and dependencies in an empty directory or replacement host.
- Verify the archive bytes, then read the manifest and restore instructions.
- Bind the recovered instance only to loopback, a private network, or a distinct test port.
- Start it and inspect errors, missing dependencies, world state, and extension data.
- Join with an ordinary player account and check spawn, a known chunk, inventory or Ender Chest, advancements, permissions, and critical extension behavior.
- Create one test state, stop normally, start again, and confirm that the state persists.
- Record the generation used, elapsed time, differences, failure points, and owner of each correction.
Checksums prove only that restored bytes match the archive. The player path and a second boot prove that those bytes form a playable server that can continue saving.
Treat an upgrade as a migration with exit conditions
An upgrade changes both executable dependencies and mutable state. Paper’s update guide requires a backup and a stopped server before replacing the JAR, and explicitly discourages unattended automatic installation. Update notifications may be automated; production cutover still needs an operator to review compatibility and logs.
| Stage | Permitted action | Evidence required to proceed |
|---|---|---|
| Plan | Read game, server, loader, mod, and plugin release notes; build a new manifest | Dependencies close, client requirements are known, exit conditions are written |
| Rehearse | Copy an isolated instance from a verified backup and launch through a separate path and network entry | No second process writes production; the startup log is complete |
| Accept | Test login, world, permissions, extensions, saving, and comparable performance with an ordinary account | Smoke tests and performance thresholds pass; data migration is understood |
| Freeze | Schedule maintenance, stop production, and create a consistent pre-upgrade backup | Production writes stop; the backup is retrievable and registered |
| Cut over | Let the new version take ownership of the upgraded or restored world copy | The old process is stopped; the new instance owns the only production entry point |
| Observe | Check prewritten exit conditions while retaining old dependencies and the pre-upgrade backup | The agreed observation window passes with stable player path and signals |
| Close or roll back | Update the baseline, or stop the new release and restore old dependencies plus pre-upgrade state | Manifest, recovery point, result, and open issues are complete |
Write exit conditions before the maintenance window, for example:
- startup does not finish, a critical error persists, or the loader reports missing dependencies;
- a critical mod, plugin, permission, or ordinary-player path fails;
- world migration produces an unexplained warning, or chunks, player data, or extension state are abnormal;
- MSPT, save duration, or memory crosses a predefined threshold under the same workload;
- the pre-upgrade backup cannot be verified or the restore path cannot run.
Paper’s basic troubleshooting guide states that a world is upgraded when a newer version loads it and that downgrading is unsupported. Replacing the old JAR therefore restores only an executable. A real rollback restores the pre-upgrade world state together with the old extensions and Java combination. No old implementation should open the only copy of a migrated world.
The same state machine applies to a patch release, loader change, or single-plugin update. A smaller change shortens the rehearsal; it does not remove the backup, single-writer, or exit-condition requirements.
Monitoring must lead to a decision
A small server needs a few signals across distinct failure layers, not a sprawling monitoring platform:
| Layer | Minimum signals | First action after an alert |
|---|---|---|
| Process | systemd state, exit cause, consecutive restart count | Read the first complete failure log and decide whether a crash loop is active |
| Capacity | Absolute disk reserve and growth, RSS, heap and GC, per-thread CPU, I/O latency | Identify which resource will exhaust first and pause background work that amplifies the failure |
| Game loop | MSPT distribution, ticks over 50 ms, TPS, online players, chunk activity | Start the implementation-supported profiler while the issue remains active |
| Player path | Account verification, join, known-chunk load, ordinary permissions, leave and reconnect | Separate network or authentication failure from world or extension failure |
| Durability | Latest off-host backup, abnormal backup size, last restore drill, measured RTO | Mark the current RPO or RTO unmet and repair the backup chain immediately |
| External reachability | Status handshake or real connection from outside the host | Separate internal host health from Internet or VPN path failure |
The minimum read-only systemd check can be fixed as:
systemctl show minecraft -p ActiveState -p SubState -p ExecMainStatus -p NRestarts
journalctl -u minecraft -b --no-pager
Process checks suit automation. Run the real player path after every release, and use a low-frequency synthetic transaction only when a dedicated test account and safe credential boundary exist. Grant that account only the game privileges needed to complete the path.
A performance alert should trigger evidence capture. Paper’s profiling guide explicitly requires the profiler to run while the problem occurs. Automatic restart can shorten a transient incident, but it also erases the performance scene and hides recurring causes. Restart-count alerts and rate limits should hand repeated failure to an operator.
Logs, crash reports, profiler links, and backup reports may disclose player names, plugin inventories, paths, IP addresses, or host information. Review the disclosure boundary before requesting outside help, and set appropriate access and retention for production monitoring.
Troubleshoot through an evidence tree and preserve the scene
When a failure occurs, freeze the timeline and collect read-only evidence before changing anything. A minimum incident packet contains:
- current time and time zone, plus the last confirmed healthy time;
- current compatibility manifest and most recent change;
- systemd and server logs from this launch, plus any crash report;
- process exit state, restart count, and listening ports;
- disk, memory, per-thread CPU, and relevant I/O state;
- latest successful backup, latest restore drill, and descriptions from affected players;
- every attempted change and its result.
These commands read common Linux state; retain their output under the same privacy boundary as the incident:
date --iso-8601=seconds
systemctl status minecraft --no-pager
journalctl -u minecraft -b --no-pager
df -h /srv/minecraft/instance
free -h
ss -lntp
Enter a different evidence branch for each symptom:
| Symptom | Answer first | Harmful action at the scene |
|---|---|---|
| Server does not start | What is the first causal error, and do actual Java, build, and dependencies match the manifest? | Replacing Java, JARs, mods, and configuration together until the error changes |
| Process runs but players cannot join | Is the port listening, can the allowed path reach it, and why do account verification or the allowlist reject the player? | Disabling online-mode to bypass an identity problem |
| Lag or stalls | Which thread, plugin, entity, chunk, or I/O operation consumes time during the MSPT spike? | Scheduling restarts, adding heap, or copying an optimization preset first |
| High memory or OOM kill | What are heap use, RSS, GC, native memory, and the host or container limit separately? | Looking only at -Xmx and moving it near the host or container ceiling |
| World or extension anomaly after update | Which stage first migrated state, and is the pre-upgrade recovery point usable? | Letting an old release, repair tool, or more plugins continue writing the only copy |
| Suspected plugin issue | Does the log identify a plugin, and how must dependencies be grouped? | Randomly deleting half the files in the production world and restarting repeatedly |
| Disk exhausted | How much comes from worlds, logs, backup staging, and dumps? | Deleting region files, player data, or the only backup to reclaim space |
| Suspected compromise | Which hosts, accounts, extensions, and backups may be affected? | Restoring directly into the original environment while retaining old credentials |
Paper’s troubleshooting material recommends binary search after confirming that plugins induce the problem. Run the search against a world copy and keep dependent plugins in one group. Preserve the same inputs in each round and change only one group, producing a reproducible cause instead of one lucky startup.
For world damage, failed upgrades, or suspected compromise, stop production writes and preserve an incident copy first. Repair tools operate only on copies. Recovery begins from a verified, unaffected backup in an isolated environment. The original scene retains evidentiary value and does not pay the cost of experimentation.
Run an acceptance drill before calling the server ready
Replace “the process still looks alive” with failure-oriented acceptance tests:
| Test | Passing evidence | Execution boundary |
|---|---|---|
| Cold start | Starts from a stopped state, no unexplained log errors, ordinary account can join | Safe on production |
| Deliberate stop | Saves normally, exits, and remains stopped | Safe on production; record the slowest save |
| Abnormal exit and rate limit | One induced test failure causes bounded restart and an alert | Isolated instance only |
| Network boundary | Allowed path joins; disallowed path reaches neither game nor management plane | Prepare out-of-band recovery before risking the only management session |
| Player transaction | Join, reach a known chunk, run an ordinary command, create state, reconnect, and read it back | Least-privileged test account |
| Empty-directory restore | Restore an off-host backup into an empty location and pass the player transaction | Separate directory and network entry |
| Peak workload | Record MSPT, hotspots, RSS, I/O, and gameplay result under the representative scenario | Reproducible world copy or agreed production window |
| Upgrade rollback | After a failed rehearsal, restore the old combination from the pre-upgrade backup | Isolated instance only |
The acceptance packet contains at least the compatibility manifest, sanitized config diff, systemd unit and checks, network-rule snapshot, backup inventory, restore report, performance baseline, and upgrade record. Another operator reading only those artifacts should be able to identify the current release, recovery point, risks, and next action.
Run destructive tests only against isolated instances. Production acceptance concentrates on normal start and stop, the real player path, network boundaries, and read-only evidence.
Containers and panels obey the same invariants
A container or hosting panel can remove installation work, but it cannot replace operational judgment. Map its concepts back to the same model:
| Container or panel concept | Fact to retain | Question to verify |
|---|---|---|
| Image and template | Immutable version or image digest, Java, server build, generated config | Will a floating latest silently change the runtime combination on restart? |
| Volume or file manager | The only production location for worlds, players, extension data, and permissions | Can two instances mount it writable at the same time? |
| Restart policy | Failure condition, backoff, count, and alert | Does manual stop remain stopped, and does a crash loop preserve evidence? |
| One-click backup | Consistency method, target failure domain, retention, encryption, restore report | Can an archive marked successful by the panel restore into an empty instance? |
| One-click update | Old and new manifests, maintenance window, acceptance, pre-upgrade recovery point | Can the update rehearse on a copy and restore old world state on failure? |
| Memory limit | Container ceiling, -Xmx, RSS, GC, and OS headroom | Does the ceiling leave room for native memory and backup tools? |
Rebuilding a container recreates the executable environment while its volume may remain damaged. A panel snapshot proves that the platform performed an action. Automatic “latest” downloads actively defeat reproducibility. Prefer a tool that can export a manifest, isolate a copy, retain multiple recovery points, bound restarts, and support a real restore drill.
Final operations checklist
First deployment
- Exact game, server, loader, Java, extensions, origins, and hashes are recorded.
- The operator read and accepted the EULA; public or paid use boundaries were reviewed.
- The service uses a dedicated low-privilege account; its systemd unit passed validation and real start or stop tests.
- Only the instance path is writable, and every added sandbox restriction passed against the complete extension set.
- Game and management entry points are separate; IPv4, IPv6, cloud, and host rules were all checked.
- Direct connections retain account verification; invite-only play uses a player allowlist.
- RPO, RTO, backup target, and retention window are written down.
- At least one backup resides in another failure domain and passed an empty-directory restore.
- The ordinary-player transaction and representative-load baseline are saved.
- Monitoring detects process, capacity, tick, player-path, and backup failure.
Each backup and restore cycle
- The backup comes from a stopped stable state or a documented consistency procedure.
- Worlds, players, extension data, configuration, permissions, manifest, and launch material are in scope.
- The latest successful copy meets the RPO and its target does not share the source-host failure.
- Size, file inventory, and integrity information show no anomaly.
- A restore drill completed ordinary-player read, write, and another startup.
- Measured restore time meets the RTO, and every problem entered the next correction cycle.
Each change and upgrade
- Purpose, exact diff, compatibility sources, and exit conditions are written.
- The new combination rehearsed against a separate world copy and entry point.
- A consistent pre-upgrade backup is registered and retrievable.
- Exactly one process writes the production world at all times.
- Ordinary-player path, critical extensions, save or restart, and comparable performance all pass.
- Automatic restart did not hide recurring failure; logs and profiler evidence are retained.
- Rollback combines old dependencies with pre-upgrade world state, never a migrated world with an old release.
- Baseline updates and temporary-copy cleanup wait until the observation window ends.
Sources, applicability, and freshness boundaries
This essay was researched again on 2026-08-11. Sources are grouped by purpose:
- Mojang and Minecraft: Java Edition server download, EULA, and Usage Guidelines;
- Paper: getting started and Java requirements, server properties, plugin privilege boundary, updates, troubleshooting, profiling, and Velocity backend security;
- mod loaders: Fabric server installation and the NeoForge user and server guide;
- Linux service boundaries:
systemd.service(5),systemd.exec(5),systemd-analyze(1), and the Ubuntu firewall guide; - recovery method: NIST SP 800-34 Rev. 1 and the CISA #StopRansomware Guide;
- JVM diagnosis: Oracle Java 26 Diagnostic Tools.
Java compatibility tables, server defaults, loader scripts, policies, and tool interfaces are time-sensitive. Reopen the primary documentation for the target release when carrying out work. The enduring structure is the set of single-writer, reproducibility, recoverability, and observability invariants, plus rehearsal before migration.
This is an operations method for a small Java Edition server. It is not legal advice, a security guarantee, or an architecture for a large public network. Paid service, prominent brand use, or broad public access needs separate policy, privacy, moderation, abuse-resistance, and DDoS analysis.
Comments
Comments are public and stored in GitHub Discussions. This page connects to giscus.app and GitHub and sends the current page path only after you show comments manually or enable automatic loading. The first load is about 0.13 MB; actual usage varies with comment content. Do not include private information.